
Robots.txt decides which AI crawlers reach your site, and llms.txt is an optional guide AI search bots rarely read.
The short version: robots.txt controls which crawlers can access your site, and every major AI company documents how its crawlers follow it. The llms.txt file is an optional Markdown guide to your best content, and AI search crawlers almost never request it.
So if the goal is visibility in ChatGPT, Perplexity, Claude, or Google’s AI Overviews, robots.txt is the file that matters. An llms.txt file earns its keep with a different audience: coding assistants and AI agents that need a fast map of your docs, pricing, and product facts.
That’s a reversal from how this topic was pitched in 2025 (even in earlier versions of this guide). Below: what each file does, what 2026 server logs show about who reads them, and copy-ready configurations for both.
What Is the Difference Between llms.txt and robots.txt?
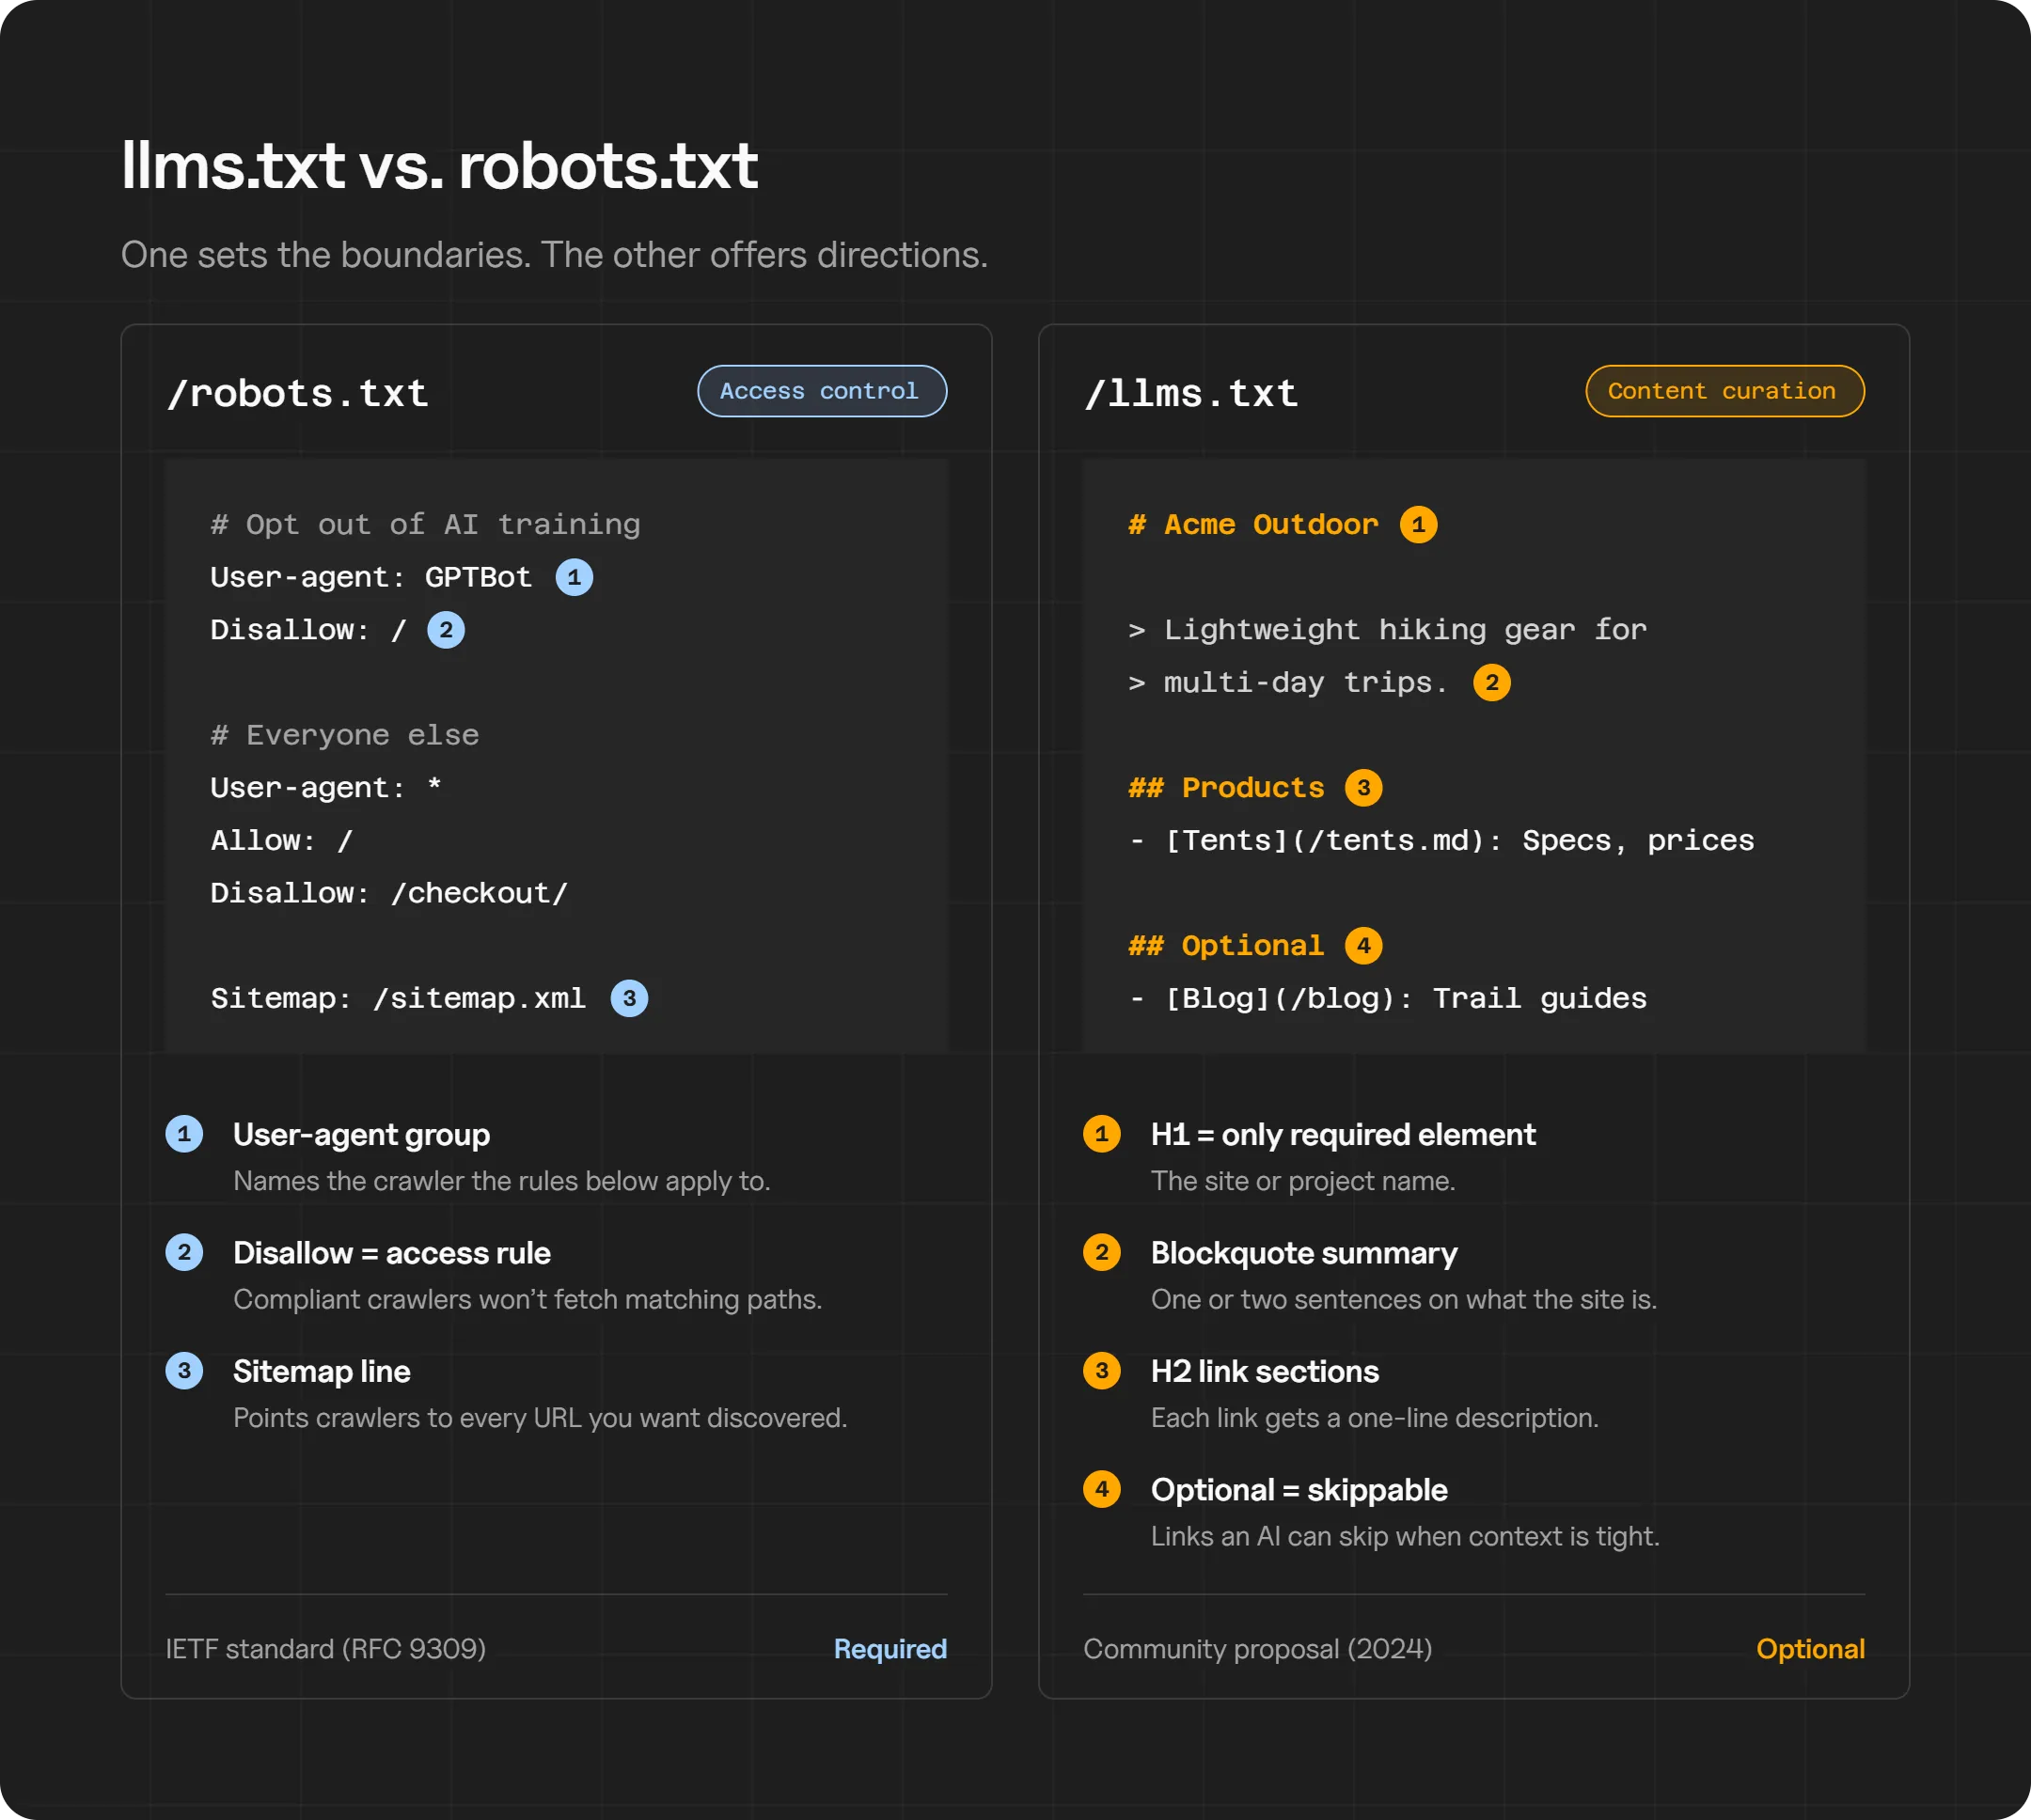
Think of robots.txt as access control. It tells crawlers which URLs they’re allowed to fetch, and it’s been an IETF standard since 2022. llms.txt is content curation: a Markdown file, proposed in 2024, that points AI models to the pages worth reading. One sets the boundaries, and the other offers directions, and only robots.txt has buy-in from the companies that run AI crawlers.
| Aspect | robots.txt | llms.txt |
| Job | Access control: which URLs crawlers may fetch | Content curation: which pages an AI should read first |
| Format | Plain-text directives (User-agent, Allow, Disallow, Sitemap) | Markdown: an H1, a summary blockquote, and H2 sections of links |
| Status | IETF standard (RFC 9309, 2022) | Community proposal (llmstxt.org, 2024) |
| Who reads it | Googlebot, Bingbot, GPTBot, OAI-SearchBot, ClaudeBot, PerplexityBot, and most legitimate crawlers | Mostly SEO audit tools, coding agents, and OpenAI’s GPTBot |
| Effect on AI search visibility | Direct: blocking a search crawler removes you from that platform’s answers | None measurable: Google says Search ignores it, and AI search bots rarely fetch it |
| Effect on AI training | Direct: blocking training crawlers (GPTBot, ClaudeBot, Google-Extended) opts you out | None |
| Cost of getting it wrong | High: one bad Disallow can hide a site from AI search | Low: an outdated file mostly goes unread |
| Priority | Required | Optional (worth it for docs-heavy sites) |
What Is llms.txt?
An llms.txt file is a Markdown document hosted at your domain root (yourdomain.com/llms.txt) that gives large language models a short summary of your site plus links to its most useful pages. Jeremy Howard (co-founder of Answer.AI), proposed it on September 3, 2024, and the spec lives at llmstxt.org. The original use case was inference time: helping a model answer a question about, say, a software library by pointing it straight to the right docs instead of making it parse navigation menus and scripts.
The spec keeps the format simple:
- An H1 with the site or project name (the only required element)
- A blockquote with a one- or two-sentence summary
- Optional paragraphs of context
- H2 sections containing lists of links, each followed by a short description
- An “Optional” section for secondary links an AI can skip when its context window is tight
Here’s a simplified llms.txt for a company:
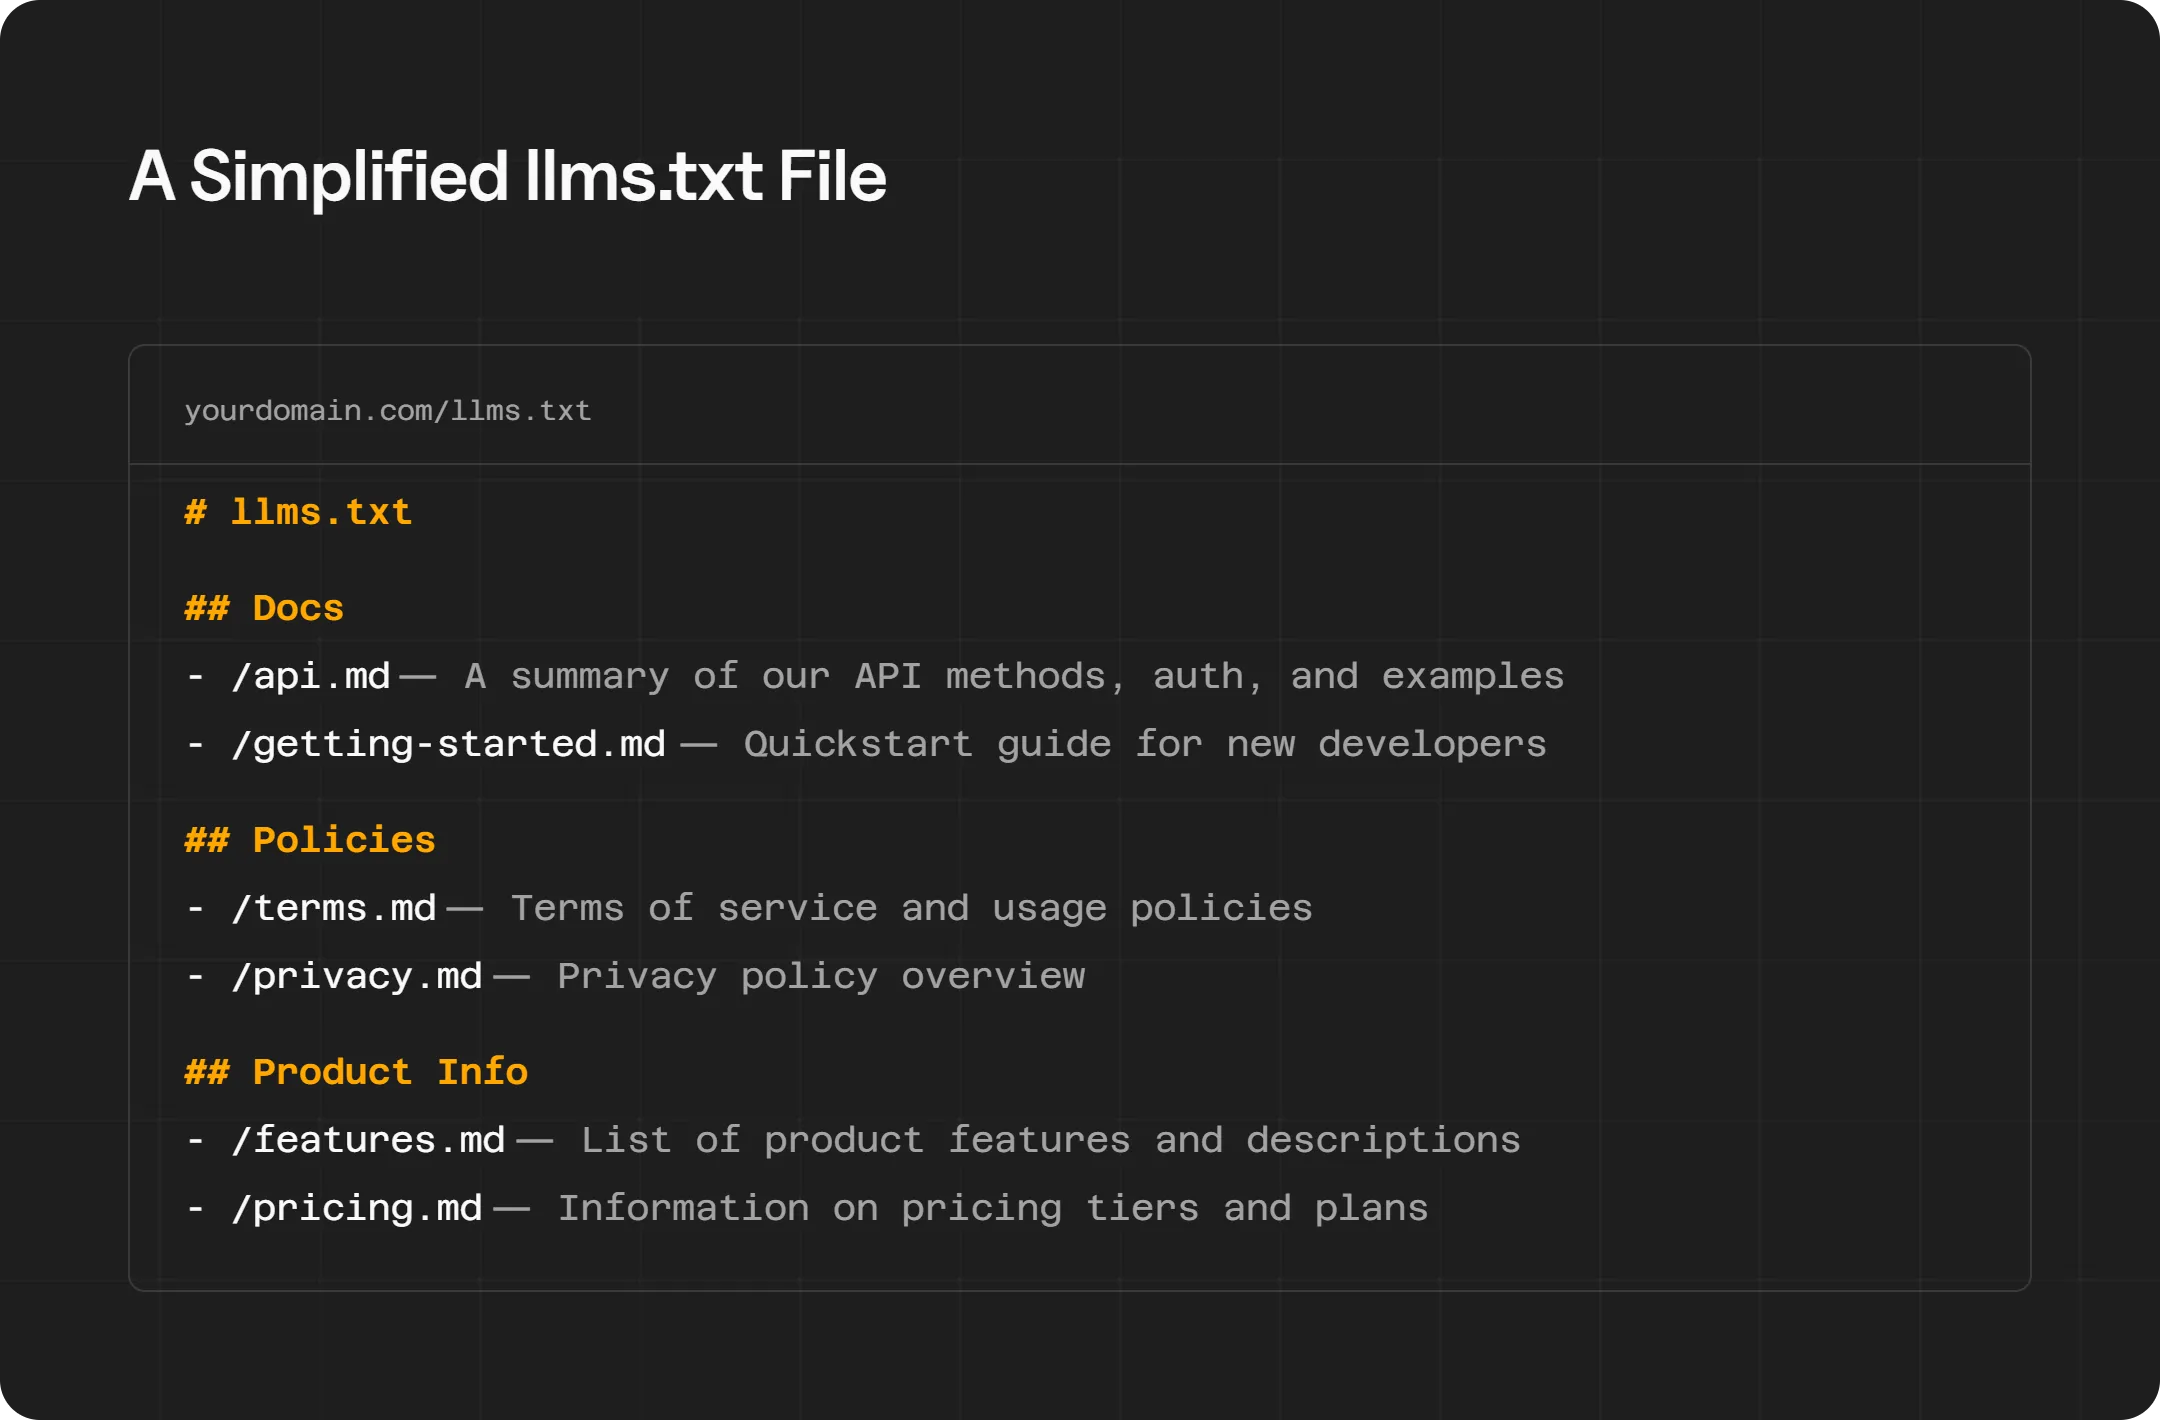
The spec also suggests publishing clean Markdown copies of key pages at the same URL with .md appended (yoursite.com/docs/api.md). Some docs platforms go a step further and generate llms-full.txt, a single file containing the full text of the documentation.
What Is robots.txt?
A robots.txt file is a plain-text file at your domain root that tells crawlers which paths they can and can’t fetch. The convention dates to 1994 and became an IETF standard as RFC 9309 in September 2022. Every major search engine and AI company documents how its crawlers interpret it, which makes it the closest thing the web has to a shared contract with bots.
The file is a list of groups. Each group names one or more user agents, followed by the rules that apply to them:
User-agent: GPTBot
Disallow: /
User-agent: *
Allow: /
Disallow: /checkout/
Sitemap: https://yourdomain.com/sitemap.xml
Two limits to understand before relying on it:
- It’s voluntary. Legitimate crawlers follow it; scrapers that spoof user agents don’t. Hard enforcement happens at your server or CDN, which is also where well-meaning sites accidentally lock AI crawlers out (see our breakdown of Cloudflare blockages).
- It governs crawling. Indexing is a separate control. A disallowed URL can still show up in Google if other pages link to it, so use a noindex tag to keep a page out of results (Google’s robots.txt documentation spells this out).
Do AI Crawlers Actually Read llms.txt?
Rarely, and the crawlers that drive AI search visibility almost never do. Large-scale server logs, Google’s own guidance, and our data all point the same way.
Server Logs Show Near-Zero AI Search Requests
Ahrefs’ analysis of May 2026 server logs across 137,210 domains found that about 28% published a valid llms.txt, and 97% of those files received zero requests that month. Among the few requests that did happen, AI retrieval bots (the ones behind ChatGPT search and Perplexity answers) accounted for roughly 1.1%, while SEO audit tools accounted for 21.7%. No AI bot requested llms.txt on sites that didn’t have one, a sign that crawlers aren’t checking for it the way they check robots.txt.
What Goodie’s Own Logs Show
We ran the same check on higoodie.com using Goodie’s AI Agent Analytics. Between May 18 and November 2, 2026, bots requested our robots.txt 736 times, including 188 fetches from AI search and retrieval bots like OAI-SearchBot, Claude-User, and PerplexityBot. Our llms.txt didn’t log a single request in the same window.
Meanwhile, AI agents fetched this article 1,008 times between August 4 and November 2, 2026, and ChatGPT-User accounted for 610 of those visits. AI search systems go straight to the pages a user’s question calls for. The table of contents never enters the picture.
Google Says Search Ignores It
Google’s guide to optimizing for generative AI features from May 2026 lists llms.txt among the tactics site owners can skip. A June update added that maintaining llms.txt files won’t hurt or help visibility in Google Search, including AI Overviews and AI Mode, because Search doesn’t use them. John Mueller has also called the format purely speculative until an AI platform actually requires it.
Who Does Read llms.txt
Coding agents, agentic browsers, and one training crawler. In the same Ahrefs data, OpenAI’s GPTBot was the most frequent named fetcher, and Claude Code out-fetched every AI retrieval bot and assistant. Chrome’s Lighthouse also added an experimental Agentic Browsing audit that checks for the file (Google’s guidance now splits by product). That’s also why AI companies publish llms.txt files for their own developer docs: both OpenAI’s and Perplexity’s documentation point agents to one.
The real job for llms.txt is agent experience (AX): making your docs, pricing, and product facts easy to find for an agent acting on someone’s behalf. If you run a developer product, an API, or a large help center, that’s worth an hour of work. If you’re hoping for more ChatGPT citations, spend the hour elsewhere.
What AI Crawlers Read Instead
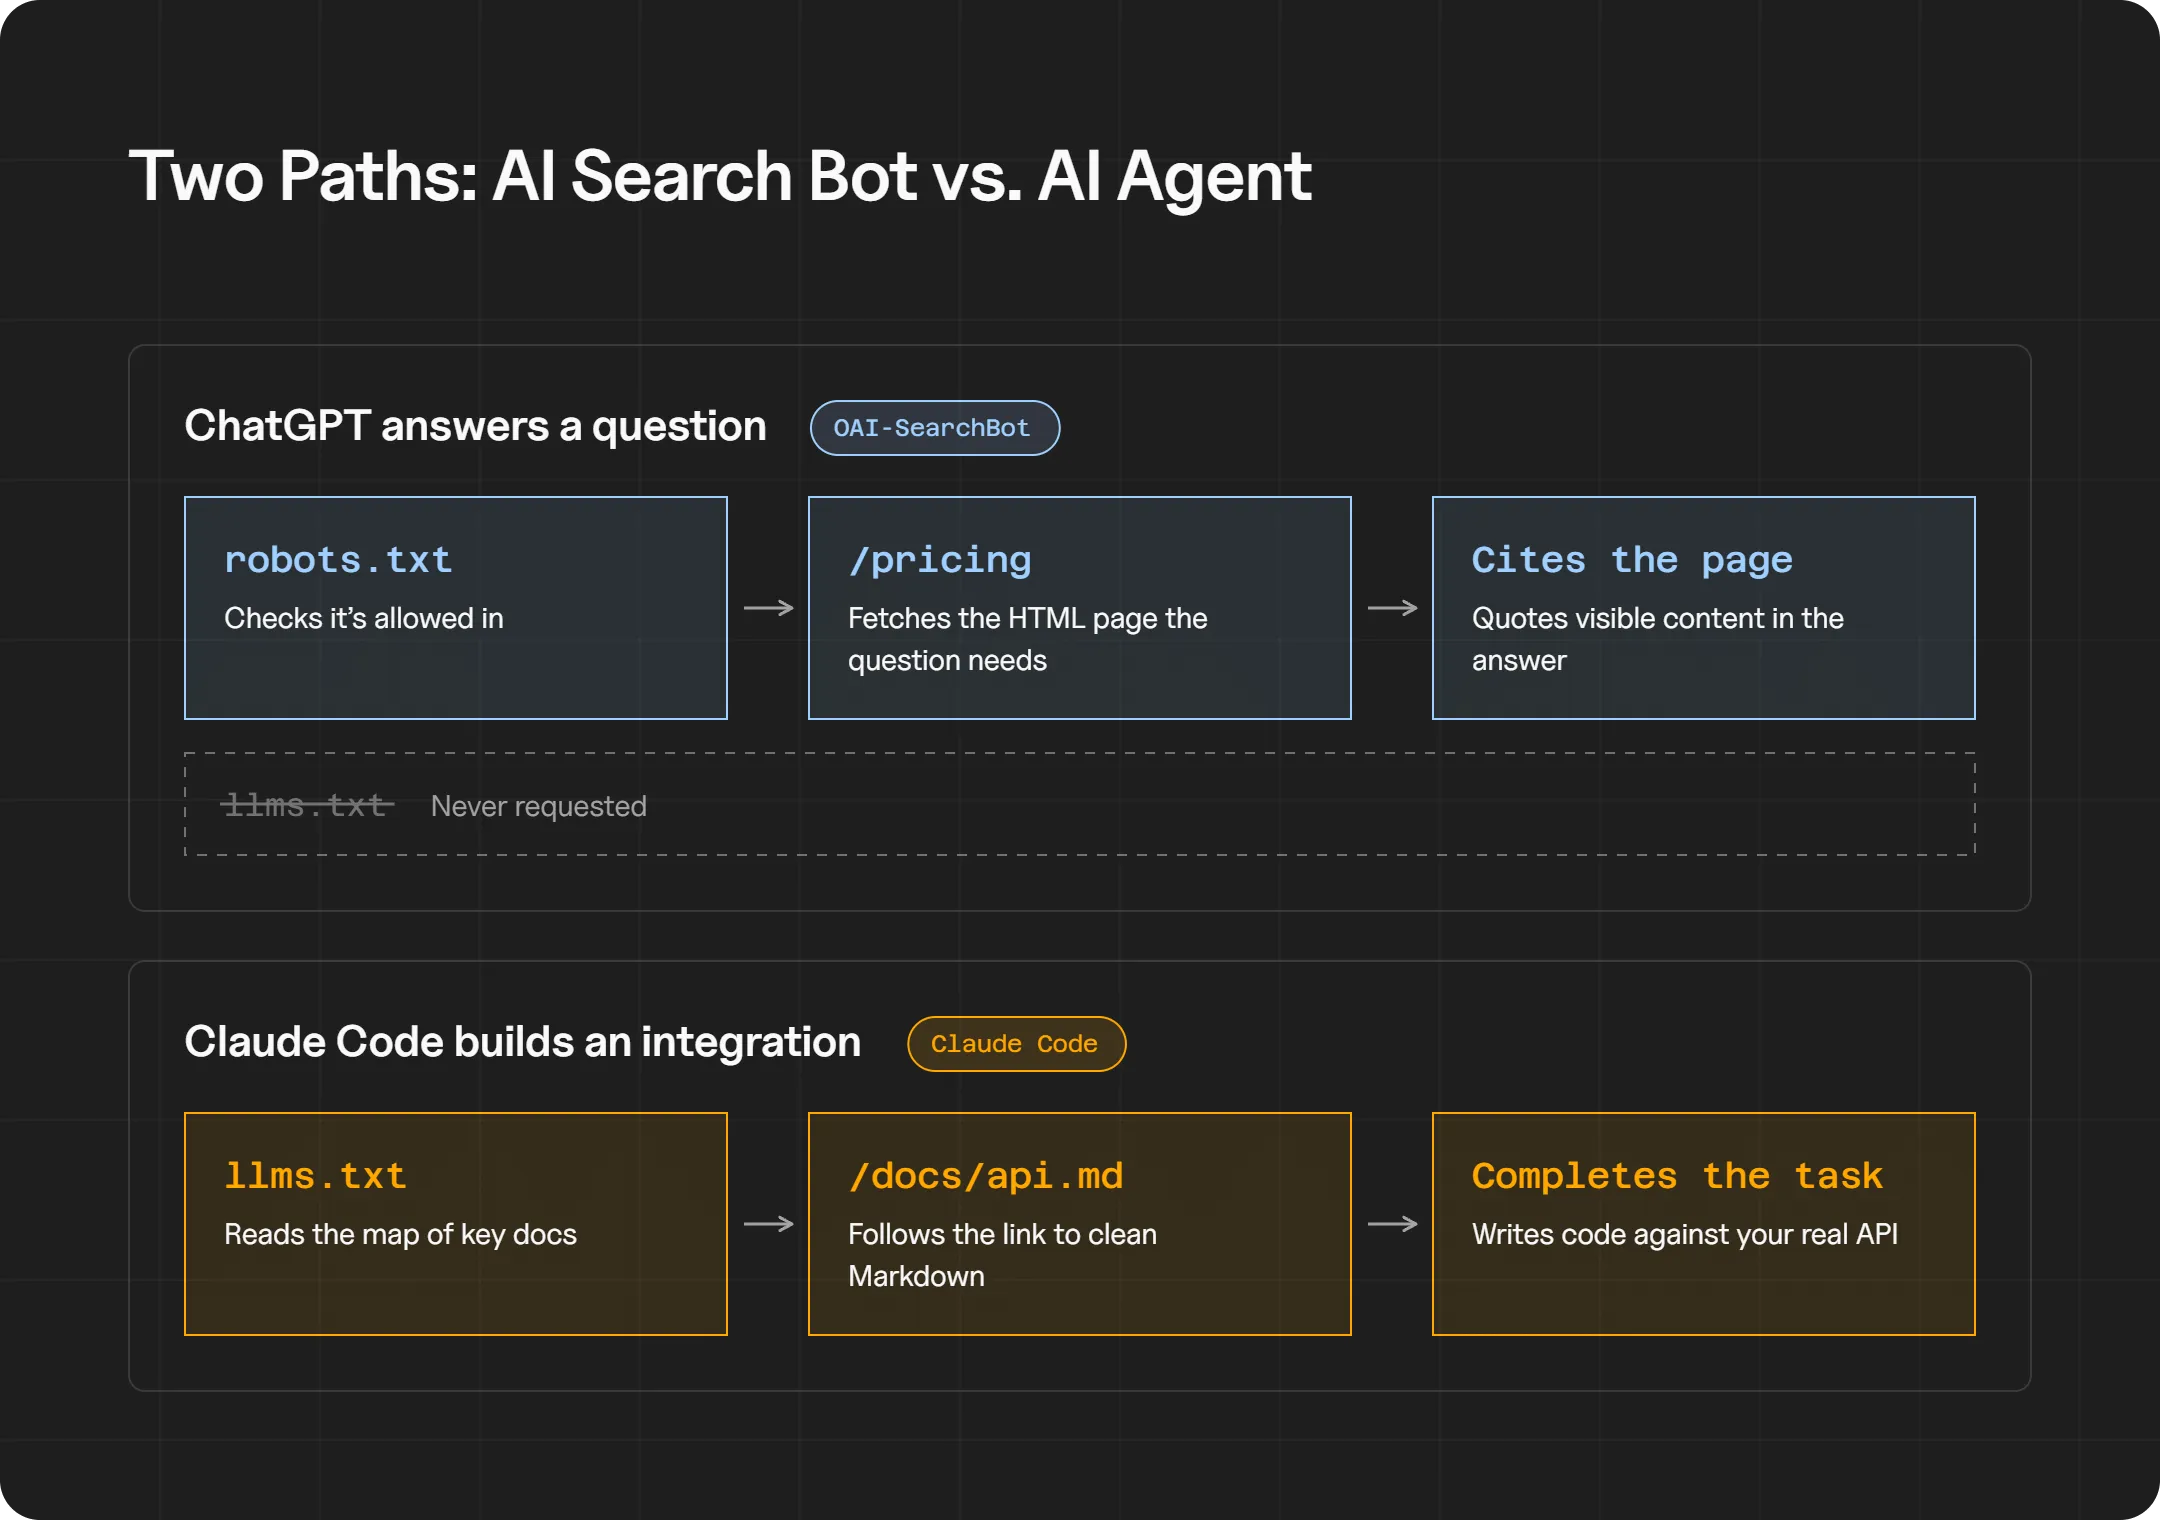
Your HTML. Most AI crawlers fetch pages without executing JavaScript (Vercel’s crawler data shows ChatGPT and Claude requesting JS files they never run), so anything rendered client-side is invisible to them. Server-side rendering, fast responses, and clean heading structure do more for answer engine optimization (AEO) than any text file. The same rule applies to schema markup: AI systems quote the visible page, so markup only helps when it matches what’s there. Our guide to AI crawler optimization covers the rendering fixes in detail.
How Do You Use robots.txt to Control AI Crawlers?
Give each AI crawler its own group and decide by purpose: model training, search indexing, or live retrieval for a user’s question. Most AI companies run separate crawlers for these jobs, so you can opt out of training without disappearing from AI answers.
Training Crawlers vs. Retrieval Crawlers
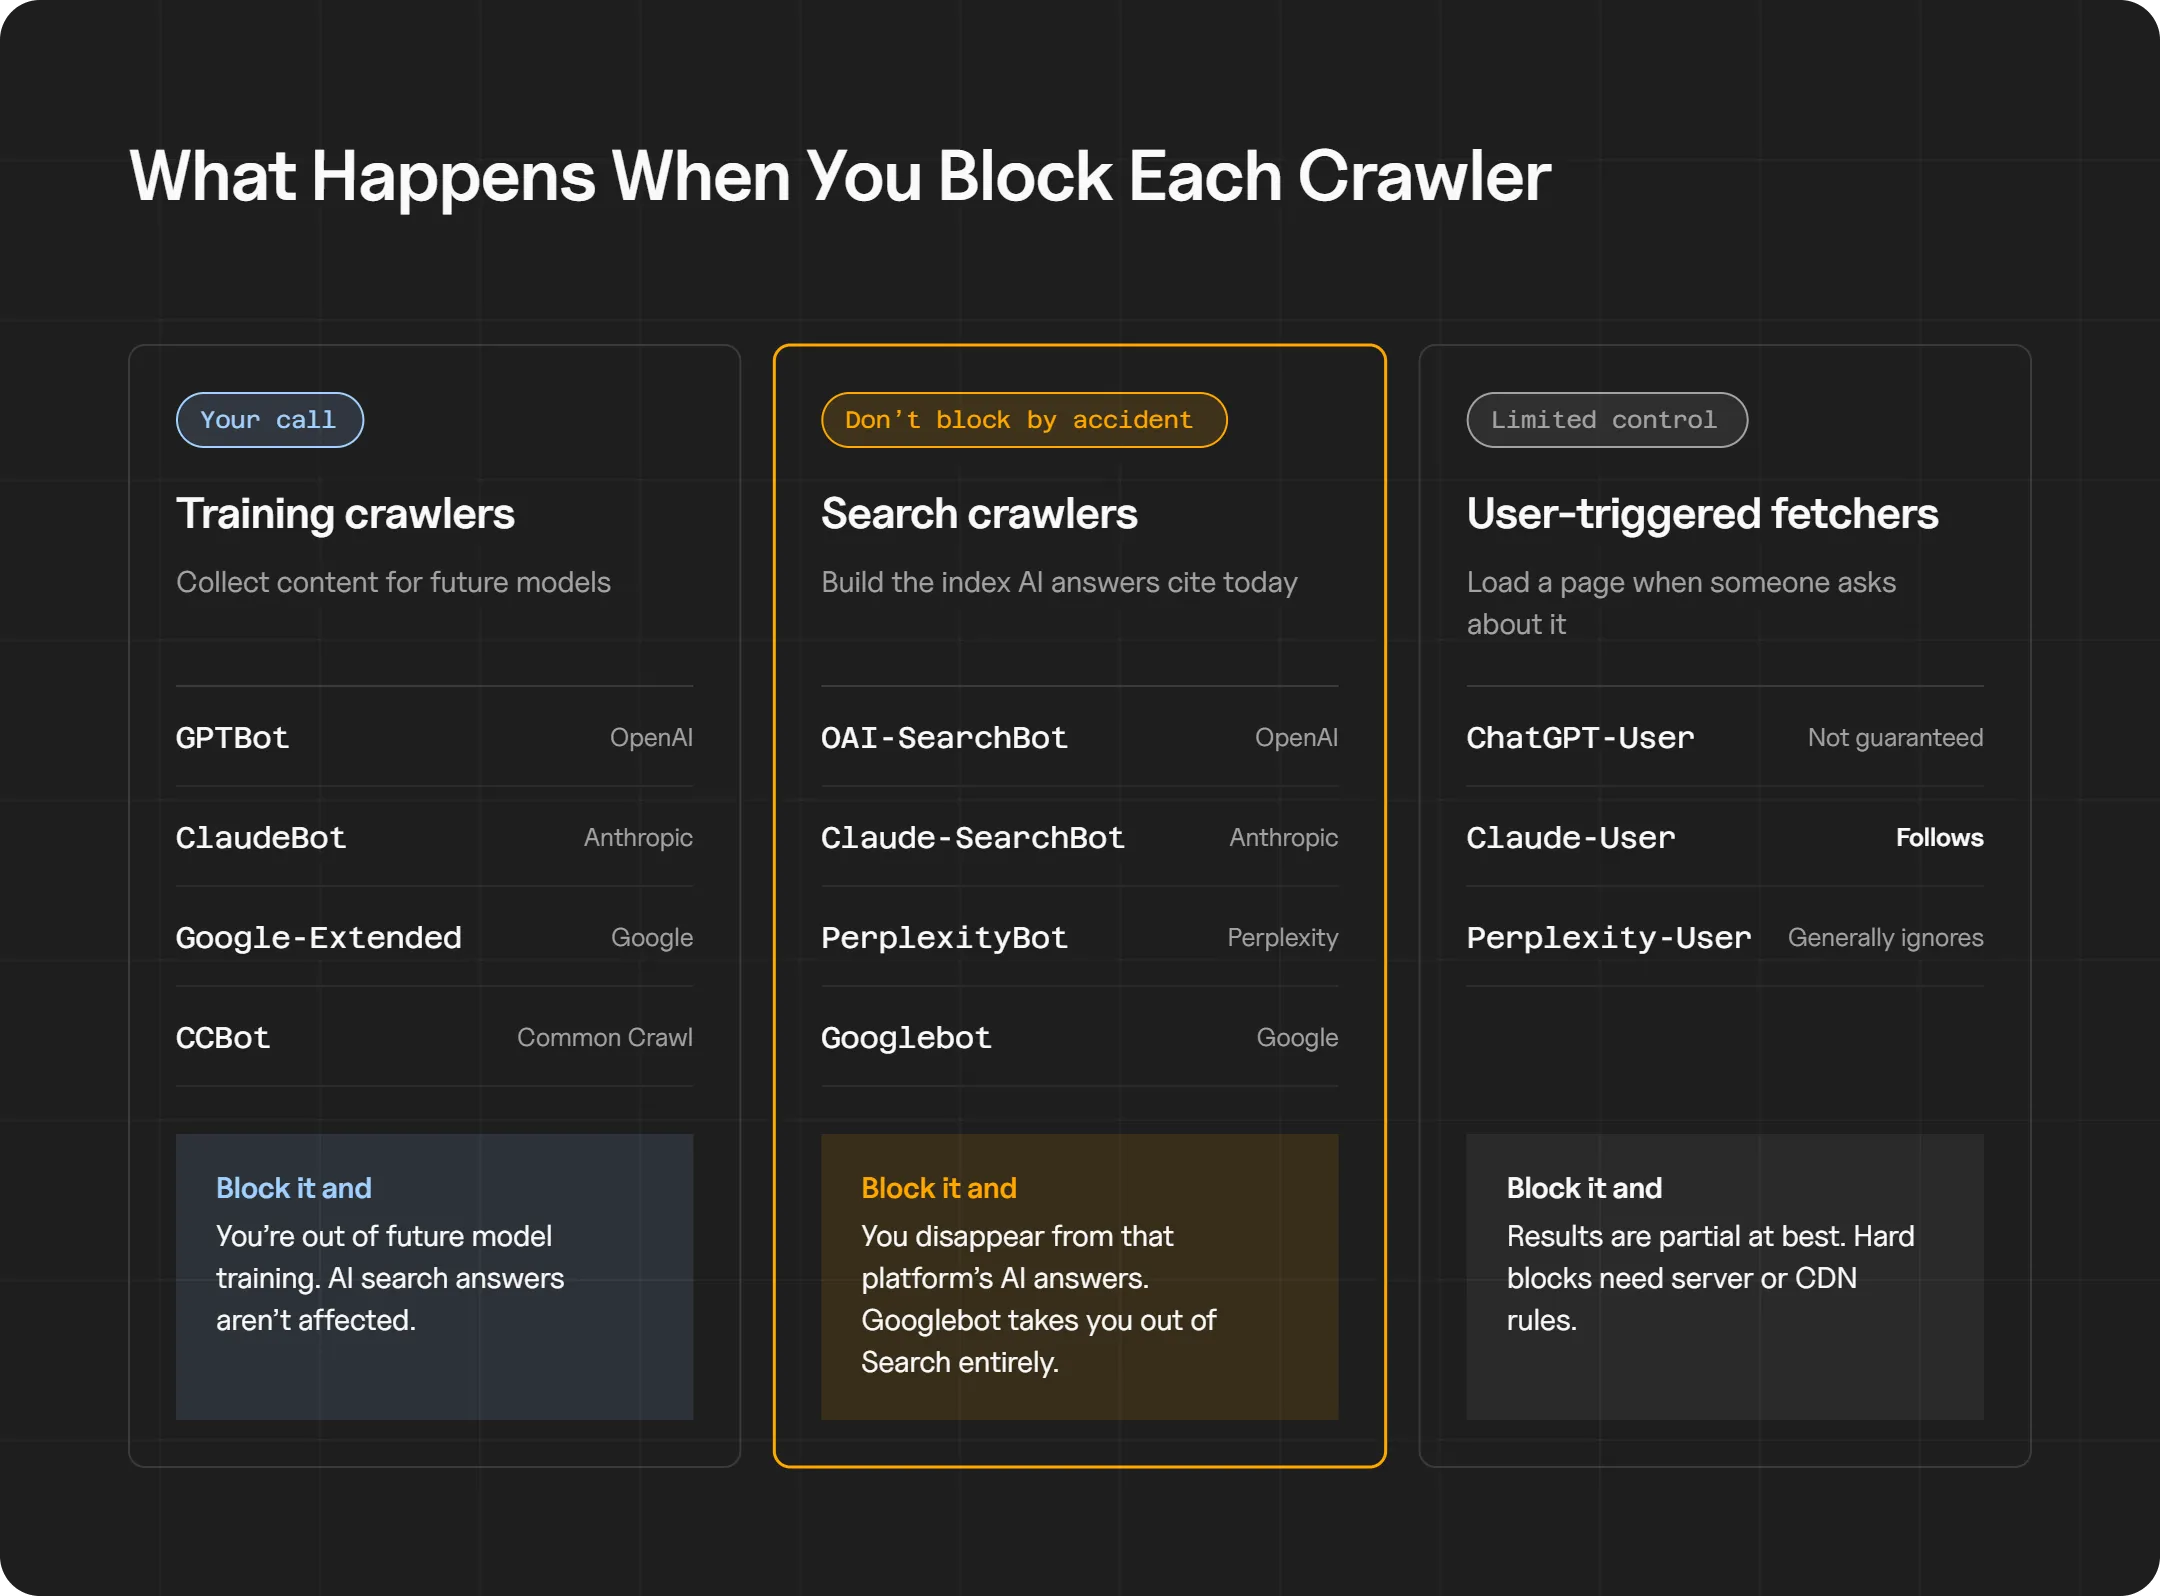
Training crawlers collect content for future models. Search crawlers build the index an AI product cites from today. User-triggered fetchers load a specific page when someone asks the assistant about it. Blocking a training crawler keeps your future content out of model training; blocking a search crawler removes you from that platform’s answers.
| Vendor | Token | Job | Follows robots.txt? | What blocking it does |
| OpenAI | GPTBot | Model training | Yes | Opts content out of training; no effect on ChatGPT search |
| OpenAI | OAI-SearchBot | ChatGPT search index | Yes | Removes pages from ChatGPT search answers (they can still appear as navigational links) |
| OpenAI | ChatGPT-User | User-triggered fetches | Not guaranteed | Limited; OpenAI says to manage search opt-outs through OAI-SearchBot |
| Anthropic | ClaudeBot | Model training | Yes | Excludes future content from training |
| Anthropic | Claude-SearchBot | Search indexing | Yes | Reduces visibility in Claude’s search results |
| Anthropic | Claude-User | User-triggered fetches | Yes | Stops Claude from fetching your pages for user questions |
| Perplexity | PerplexityBot | Search index (not used for training) | Yes | Removes you from Perplexity’s indexed sources |
| Perplexity | Perplexity-User | User-triggered fetches | Generally no | Little effect |
| Google-Extended | Gemini training and Gemini Apps grounding | Yes | Opts out of both; no effect on Search or AI Overviews | |
| Googlebot | Search, including AI Overviews and AI Mode | Yes | Removes you from Google Search entirely | |
| Common Crawl | CCBot | Open web archive used to train many models | Yes | Keeps future content out of Common Crawl |
Copy-Ready robots.txt Setups
Leaving robots.txt untouched means every compliant crawler is allowed. Most brands should keep search and retrieval crawlers open and make a deliberate call on training. This setup stays visible in AI answers while opting out of model training:
# Opt out of AI model training
User-agent: GPTBot
User-agent: ClaudeBot
User-agent: Google-Extended
User-agent: CCBot
Disallow: /
# Keep AI search and retrieval crawlers open
User-agent: OAI-SearchBot
User-agent: ChatGPT-User
User-agent: Claude-SearchBot
User-agent: Claude-User
User-agent: PerplexityBot
Allow: /
User-agent: *
Allow: /
Sitemap: https://yourdomain.com/sitemap.xml
Weigh two trade-offs before shipping it. Blocking Google-Extended also makes your pages ineligible for grounding in Gemini Apps, per Google. And opting out of training means future models learn about your brand from everyone else’s content. Brands that care how AI describes them often keep training crawlers open for exactly that reason.
To leave AI search entirely, add Disallow rules for OAI-SearchBot, Claude-SearchBot, Claude-User, and PerplexityBot as well. Expect your pages to drop out of ChatGPT search, Claude, and Perplexity answers soon after (OpenAI says robots.txt changes take about 24 hours to register).
The Shared AI Training Opt-Out Arriving in 2027
On October 30, 2026, Google, Microsoft, and OpenAI each committed to honoring a shared robots.txt token, __usage_ai-training, that states one training preference to every participating AI provider at once. Anthropic submitted the IETF draft behind it the same day. It uses ordinary robots.txt syntax:
User-Agent: __usage_ai-training
Disallow: /
Allow: /press-kit/
Rollouts differ: Microsoft starts honoring it February 1, 2027, Google targets early 2027, and OpenAI hasn’t set a date. The token covers training only, so crawl access and AI search visibility still run through the per-crawler groups above. Microsoft is also adding a separate page-level grounding preference for Copilot answers.
Two related standards are still in motion. Cloudflare’s Content Signals Policy adds a Content-Signal line to robots.txt (search, ai-input, ai-train) and sets search=yes, ai-train=no by default on domains using Cloudflare’s managed robots.txt. The IETF’s AI Preferences (AIPREF) working group is drafting a broader Content-Usage rule, but neither of its drafts has reached RFC status. Both state preferences. Neither blocks anything.
Where robots.txt Stops Working
User-triggered fetchers sit in a gray zone. OpenAI says robots.txt rules “may not apply” to ChatGPT-User, and Perplexity says Perplexity-User generally ignores them, since a person started the request. For a hard block, enforce it at the server or CDN using the IP ranges OpenAI and Perplexity publish. For throttling, Crawl-delay works on some bots (Anthropic supports it), and Google ignores it.
How Do You Create an llms.txt File?
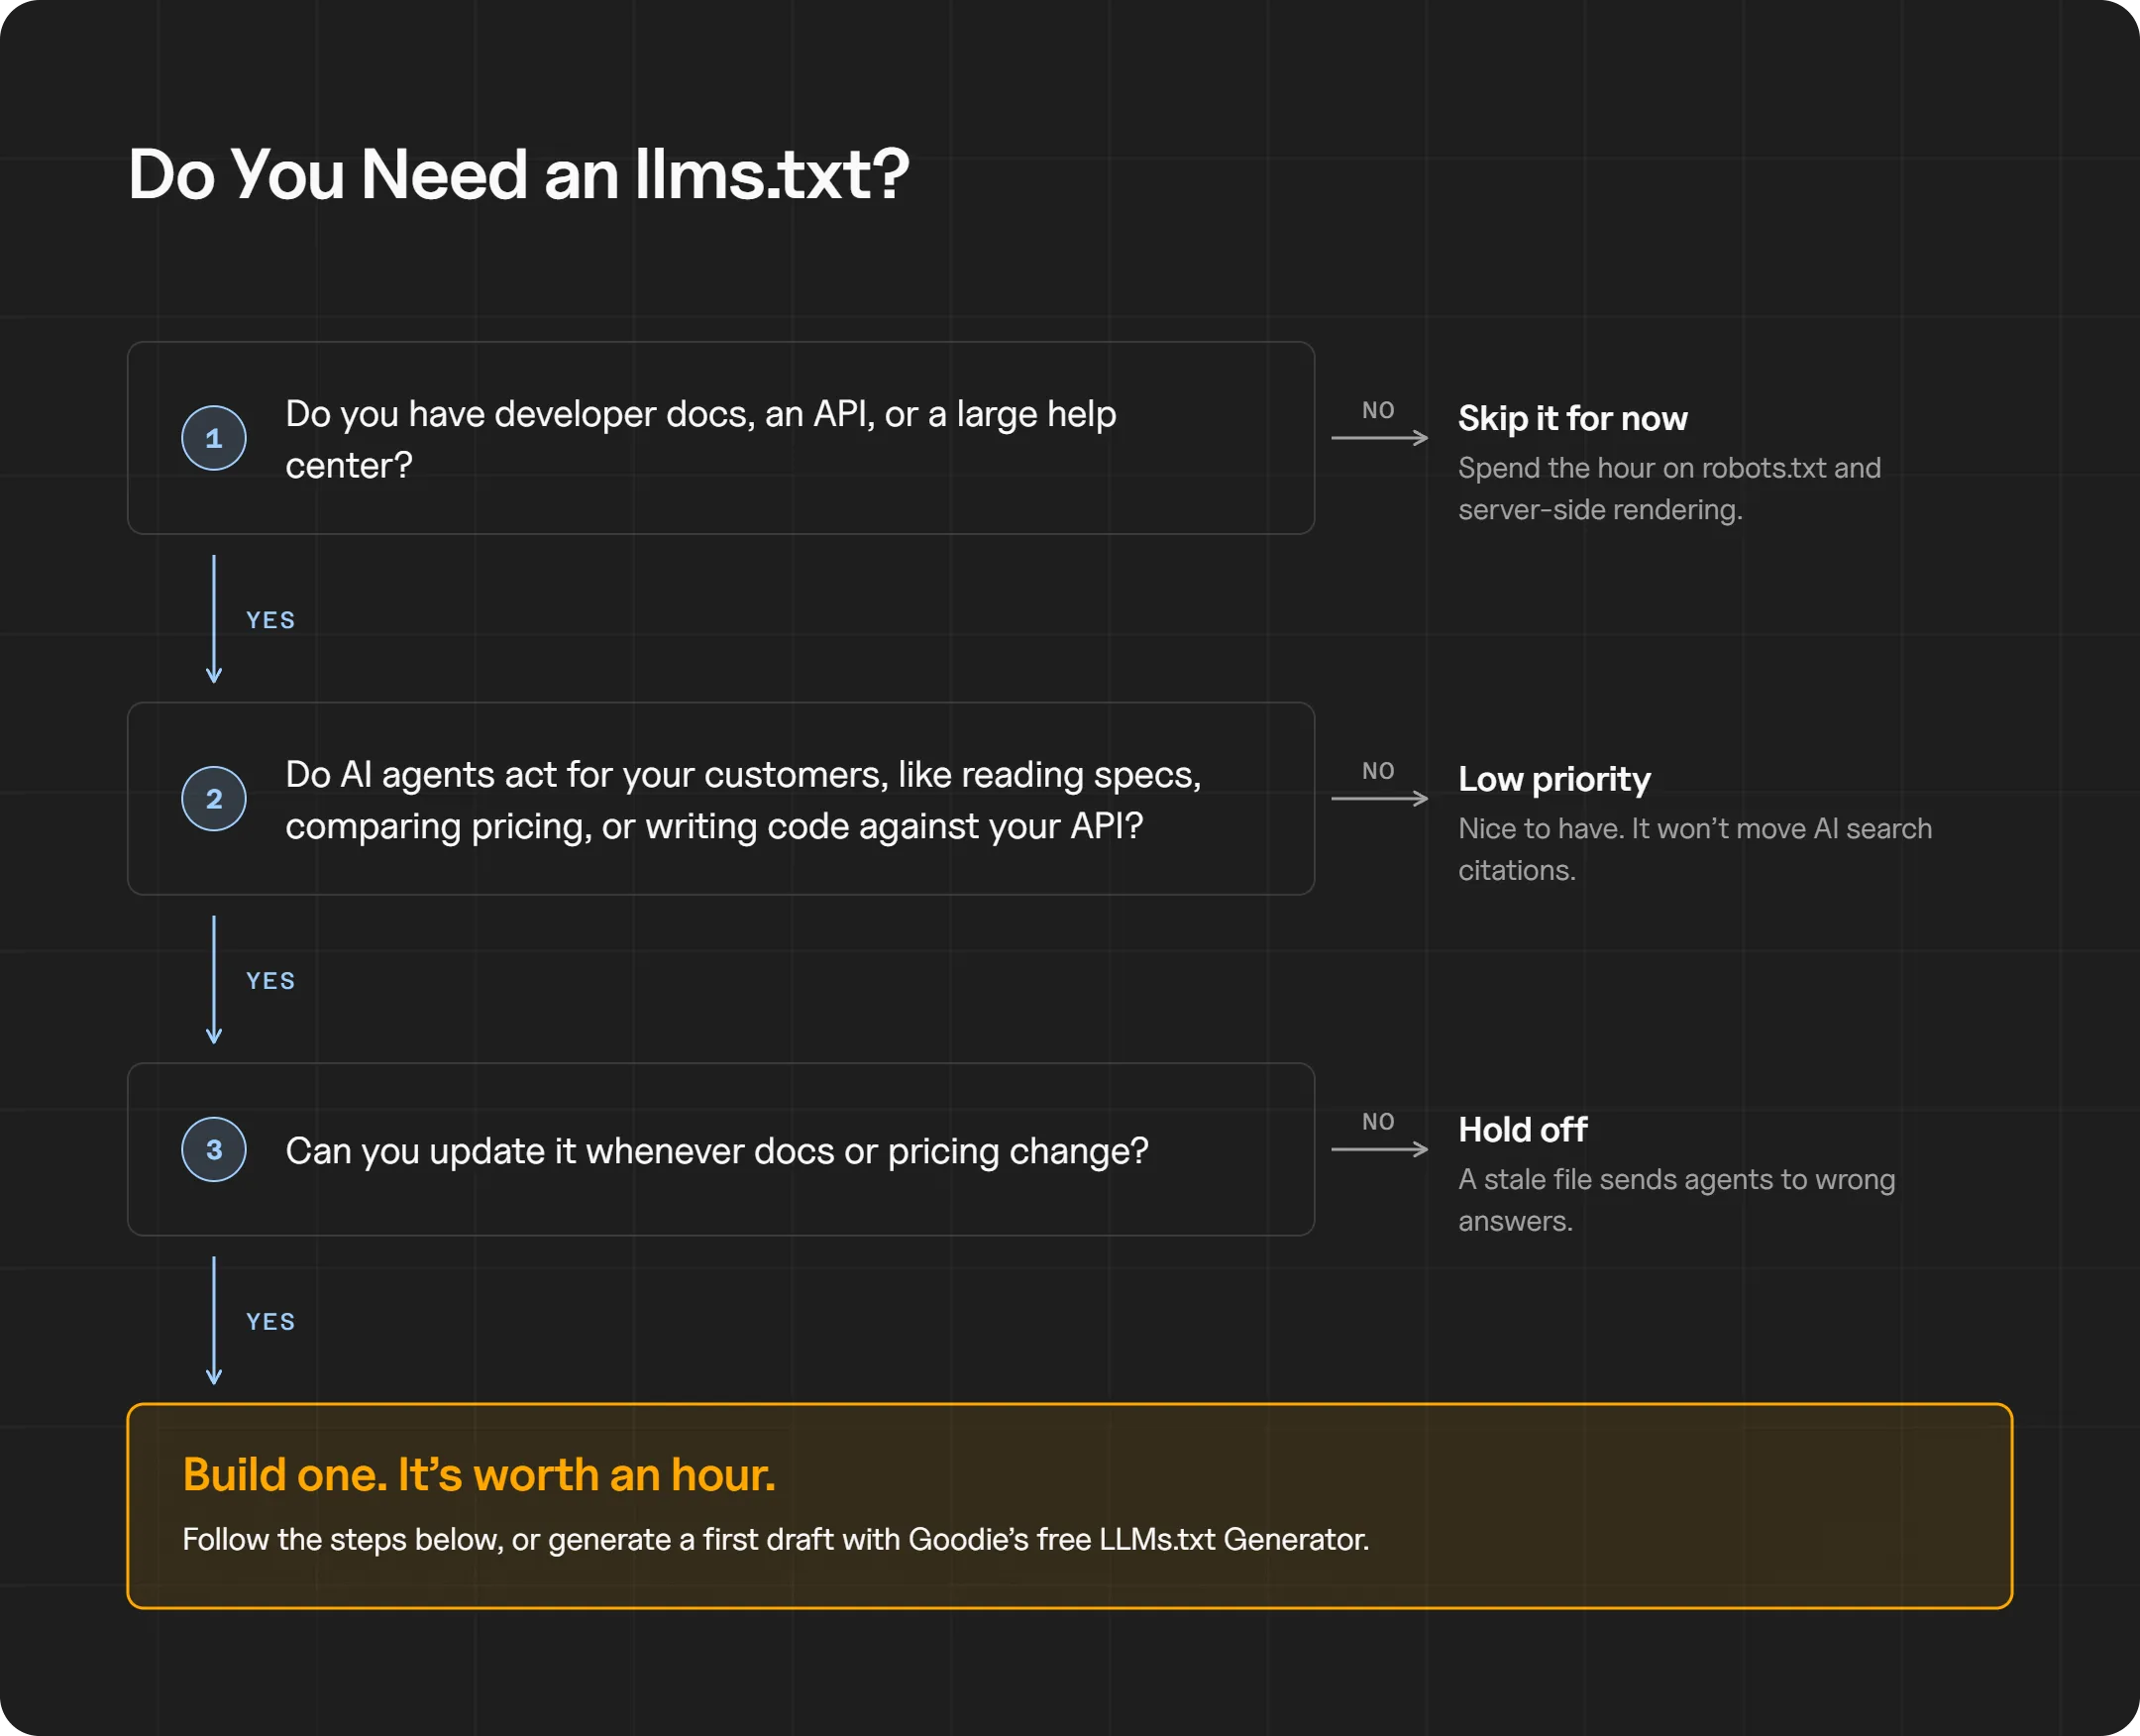
If you have developer docs, an API, or a deep help center, a basic llms.txt takes under an hour. Here’s the process:
- List the pages an agent needs most: product and API docs, pricing, specs, policies, and core company facts.
- Open the file with an H1 (your brand or product name) and a one-sentence blockquote summary.
- Group links under H2 sections, and give each link a one-line description of what the page answers.
- Link Markdown versions of key pages if your CMS or docs platform can generate them. Otherwise, link the HTML pages.
- Upload the file to your root as /llms.txt, served as plain text, and confirm robots.txt doesn’t disallow the file or the pages it lists.
- Update it whenever docs or pricing change. A stale llms.txt sends agents to wrong answers.
Goodie’s free LLMs.txt Generator builds the file from your site’s key URLs in a few minutes, and our guide to llms.txt for eCommerce covers how to structure one for large product catalogs.
Audit Your robots.txt Before You Write an llms.txt
The highest-impact move here takes ten minutes. Open your robots.txt and confirm you aren’t blocking OAI-SearchBot, Claude-SearchBot, PerplexityBot, or Googlebot by accident (a leftover wildcard Disallow or a CDN bot rule is the usual culprit). Then make a deliberate call on training crawlers, and add llms.txt if agents are part of how customers use your product.
Check What AI Crawlers Can Reach on Your Site
Goodie’s free Agent Site Audit runs 36 checks across your robots.txt, sitemap, llms.txt, and rendering to show what AI crawlers and agents can actually access. No signup required.
llms.txt vs robots.txt for AEO: FAQs
No. Google Search doesn’t use llms.txt for rankings, AI Overviews, or AI Mode, and Google says maintaining one won’t help or hurt your visibility. Chrome’s Lighthouse treats it as an optional signal for agentic browsing, which is a separate product.
Blocking OAI-SearchBot removes your pages from ChatGPT search answers, though OpenAI says they can still appear as navigational links. Blocking GPTBot only affects training. Neither stops ChatGPT from mentioning your brand, because it also learns about you from third-party sites. Once your crawler settings are in place, here’s how to track ChatGPT visibility.
The llms-full.txt file puts the full text of a site’s documentation into one Markdown file instead of linking out. It’s most useful for coding assistants that load an entire doc set into context, and it’s overkill for most marketing sites.
The ai.txt file is a permissions format Spawning introduced in 2023 to state whether AI companies can train on your text, images, audio, video, or code. Its reach depends on which dataset builders check Spawning’s API (launch partners include Hugging Face and Stability AI). For a training preference the major AI labs have committed to, use the __usage_ai-training token in robots.txt.
Yes. Search engines use your XML sitemap to discover and recrawl URLs, and those indexes feed AI features like AI Overviews and Copilot. An llms.txt file doesn’t replace it. Keep the sitemap current and list it in robots.txt with a Sitemap line.